The Rise of Micro Decision Models: Why Small Open AI Models Are Reshaping Development
Explore how ultra-small, open-source AI models and micro decision systems are changing software development. Learn why sub-billion parameter models are becoming the go-to choice for edge computing, cost-efficient automation, and local-first applications.
 admin
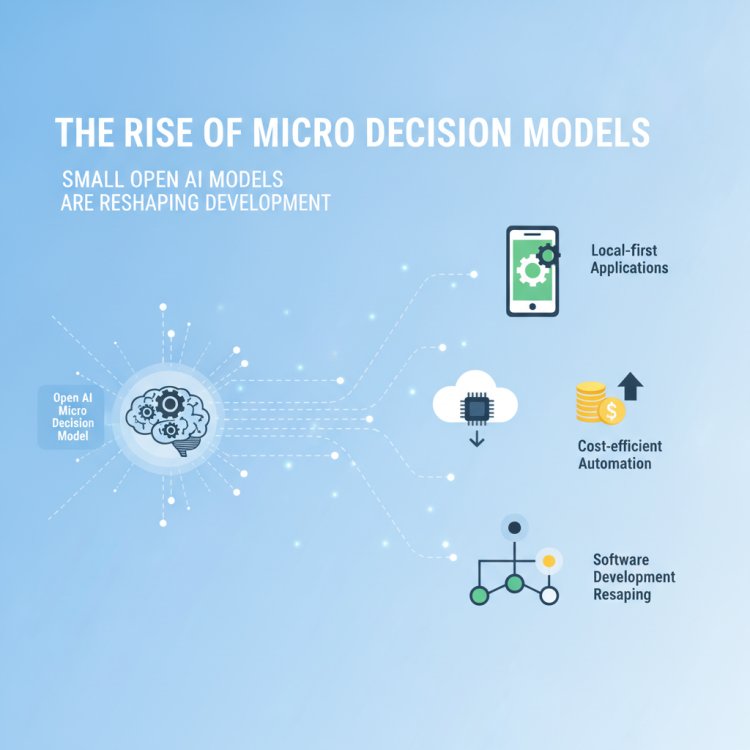
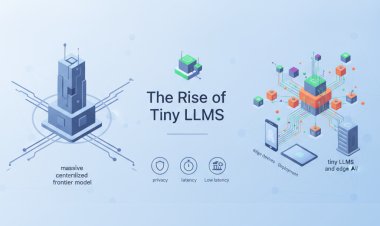
For the past few years, the narrative surrounding artificial intelligence has been dominated by scale. Every few months, major labs and open-source communities pushed out larger foundation models boasting trillions of parameters, massive context windows, and staggering hardware requirements. While these behemoths remain essential for complex, open-ended reasoning and deep creative generation, a quiet counter-revolution is taking place across the tech landscape.
Developers, enterprise IT leaders, and systems architects are increasingly turning their attention toward the opposite end of the spectrum: ultra-small, highly specialized AI models. Often sitting well under the traditional parameter thresholds—ranging from sub-billion parameter language models to compact, open-source decision engines—these micro models are proving that bigger is not always better when you need fast, deterministic, and cost-effective execution.
Let's examine what is driving this shift toward micro decision models, why they matter for modern software architecture, and how development teams can integrate them into their tech stacks.
What Changed? The Shift Toward Specialized, Lightweight AI
The sudden rise in popularity of tiny language models and micro decision systems isn't just a matter of cost-cutting; it represents a fundamental maturation in how we deploy machine learning. Earlier, trying to run local automation or edge-based routing meant compromising heavily on intelligence or relying on clunky, brittle heuristic code.
Today, open-source communities are releasing highly optimized, lightweight architectures that punch well above their weight class. These models are trained or fine-tuned for specific tasks—such as logical routing, text embedding, simple decision trees, or metadata extraction—rather than trying to be a jack-of-all-trades. Because they require minimal memory footprint and can run comfortably on standard CPU hardware or low-power edge devices, they eliminate the latency and cloud-infrastructure overhead associated with massive APIs.
Furthermore, developers are realizing that for many software engineering workflows, an oversized model introduces unnecessary variance. When you need an AI to reliably choose a code path, parse structured JSON, or filter incoming data streams, a smaller, highly focused decision model often delivers superior predictability.
Why Micro Decision Models Matter for Businesses and Developers
Transitioning workloads from massive cloud-hosted LLMs to localized or lightweight micro models offers several distinct advantages for modern technology teams:
- Radically Lower Latency: By eliminating network round-trips to remote cloud endpoints and shrinking inference time, micro models enable real-time responsiveness essential for interactive tooling, IoT devices, and fast-paced developer environments.
- Drastic Cost Reduction: Running continuous automation loops or handling high-volume background tasks with massive models quickly drains cloud budgets. Micro models can often be hosted locally or run on inexpensive serverless infrastructure for a fraction of the cost.
- Enhanced Data Privacy and Security: Handling sensitive telemetry, internal codebases, or customer data locally without sending it to third-party API providers mitigates compliance headaches and data leakage risks.
- Deterministic Control: Smaller models are easier to constrain, prompt-engineer, and fine-tune for strict output formats, reducing the frustrating hallucinations common in larger, more generalized models.
Key Integration Strategies for Development Teams
Adopting micro decision models requires a shift in engineering mindset. Instead of treating AI as an all-knowing oracle, developers should treat small models as intelligent microservices or specialized components within a larger, structured system. Here are four best practices for implementing them effectively:
- Audit Your Workloads for Narrow Tasks: Identify areas in your application where heavy models are being underutilized—such as intent classification, routing data between agents, or lightweight formatting—and benchmark them against smaller alternatives.
- Embrace Local-First and Edge Deployments: Test how sub-billion parameter models perform directly on local developer machines, edge servers, or client hardware to reduce external API dependencies.
- Combine with Traditional Logic: Do not rely entirely on the AI for rigid business logic. Use micro models to handle ambiguous classification or language understanding, and let deterministic code handle the execution paths.
- Prioritize Open-Source Ecosystems: Leverage community-driven, transparent model weights that allow you to inspect, fine-tune, and self-host without being locked into a proprietary vendor's ecosystem or pricing model.
The Future of Lightweight Machine Learning
The maturation of small, open-source AI models signals a healthy stabilization of the artificial intelligence market. As the industry moves past the initial phase of raw parameter scaling, the focus is shifting toward efficiency, accessibility, and practical utility. By embracing micro decision models, engineering teams can build faster, cheaper, and more private AI-driven features that integrate seamlessly into existing software architectures.
Whether you are designing edge infrastructure, optimizing enterprise cloud pipelines, or building developer tools, incorporating lightweight models into your toolkit is no longer just an experimental exercise—it is a competitive advantage.